3 mai 2022
de admin
0 Commentaires
3 mai 2022
de admin
0 Commentaires
28 mai 2019
de admin
0 Commentaires
28 mai 2019
de admin
0 Commentaires
10 mai 2019
de admin
Un commentaire
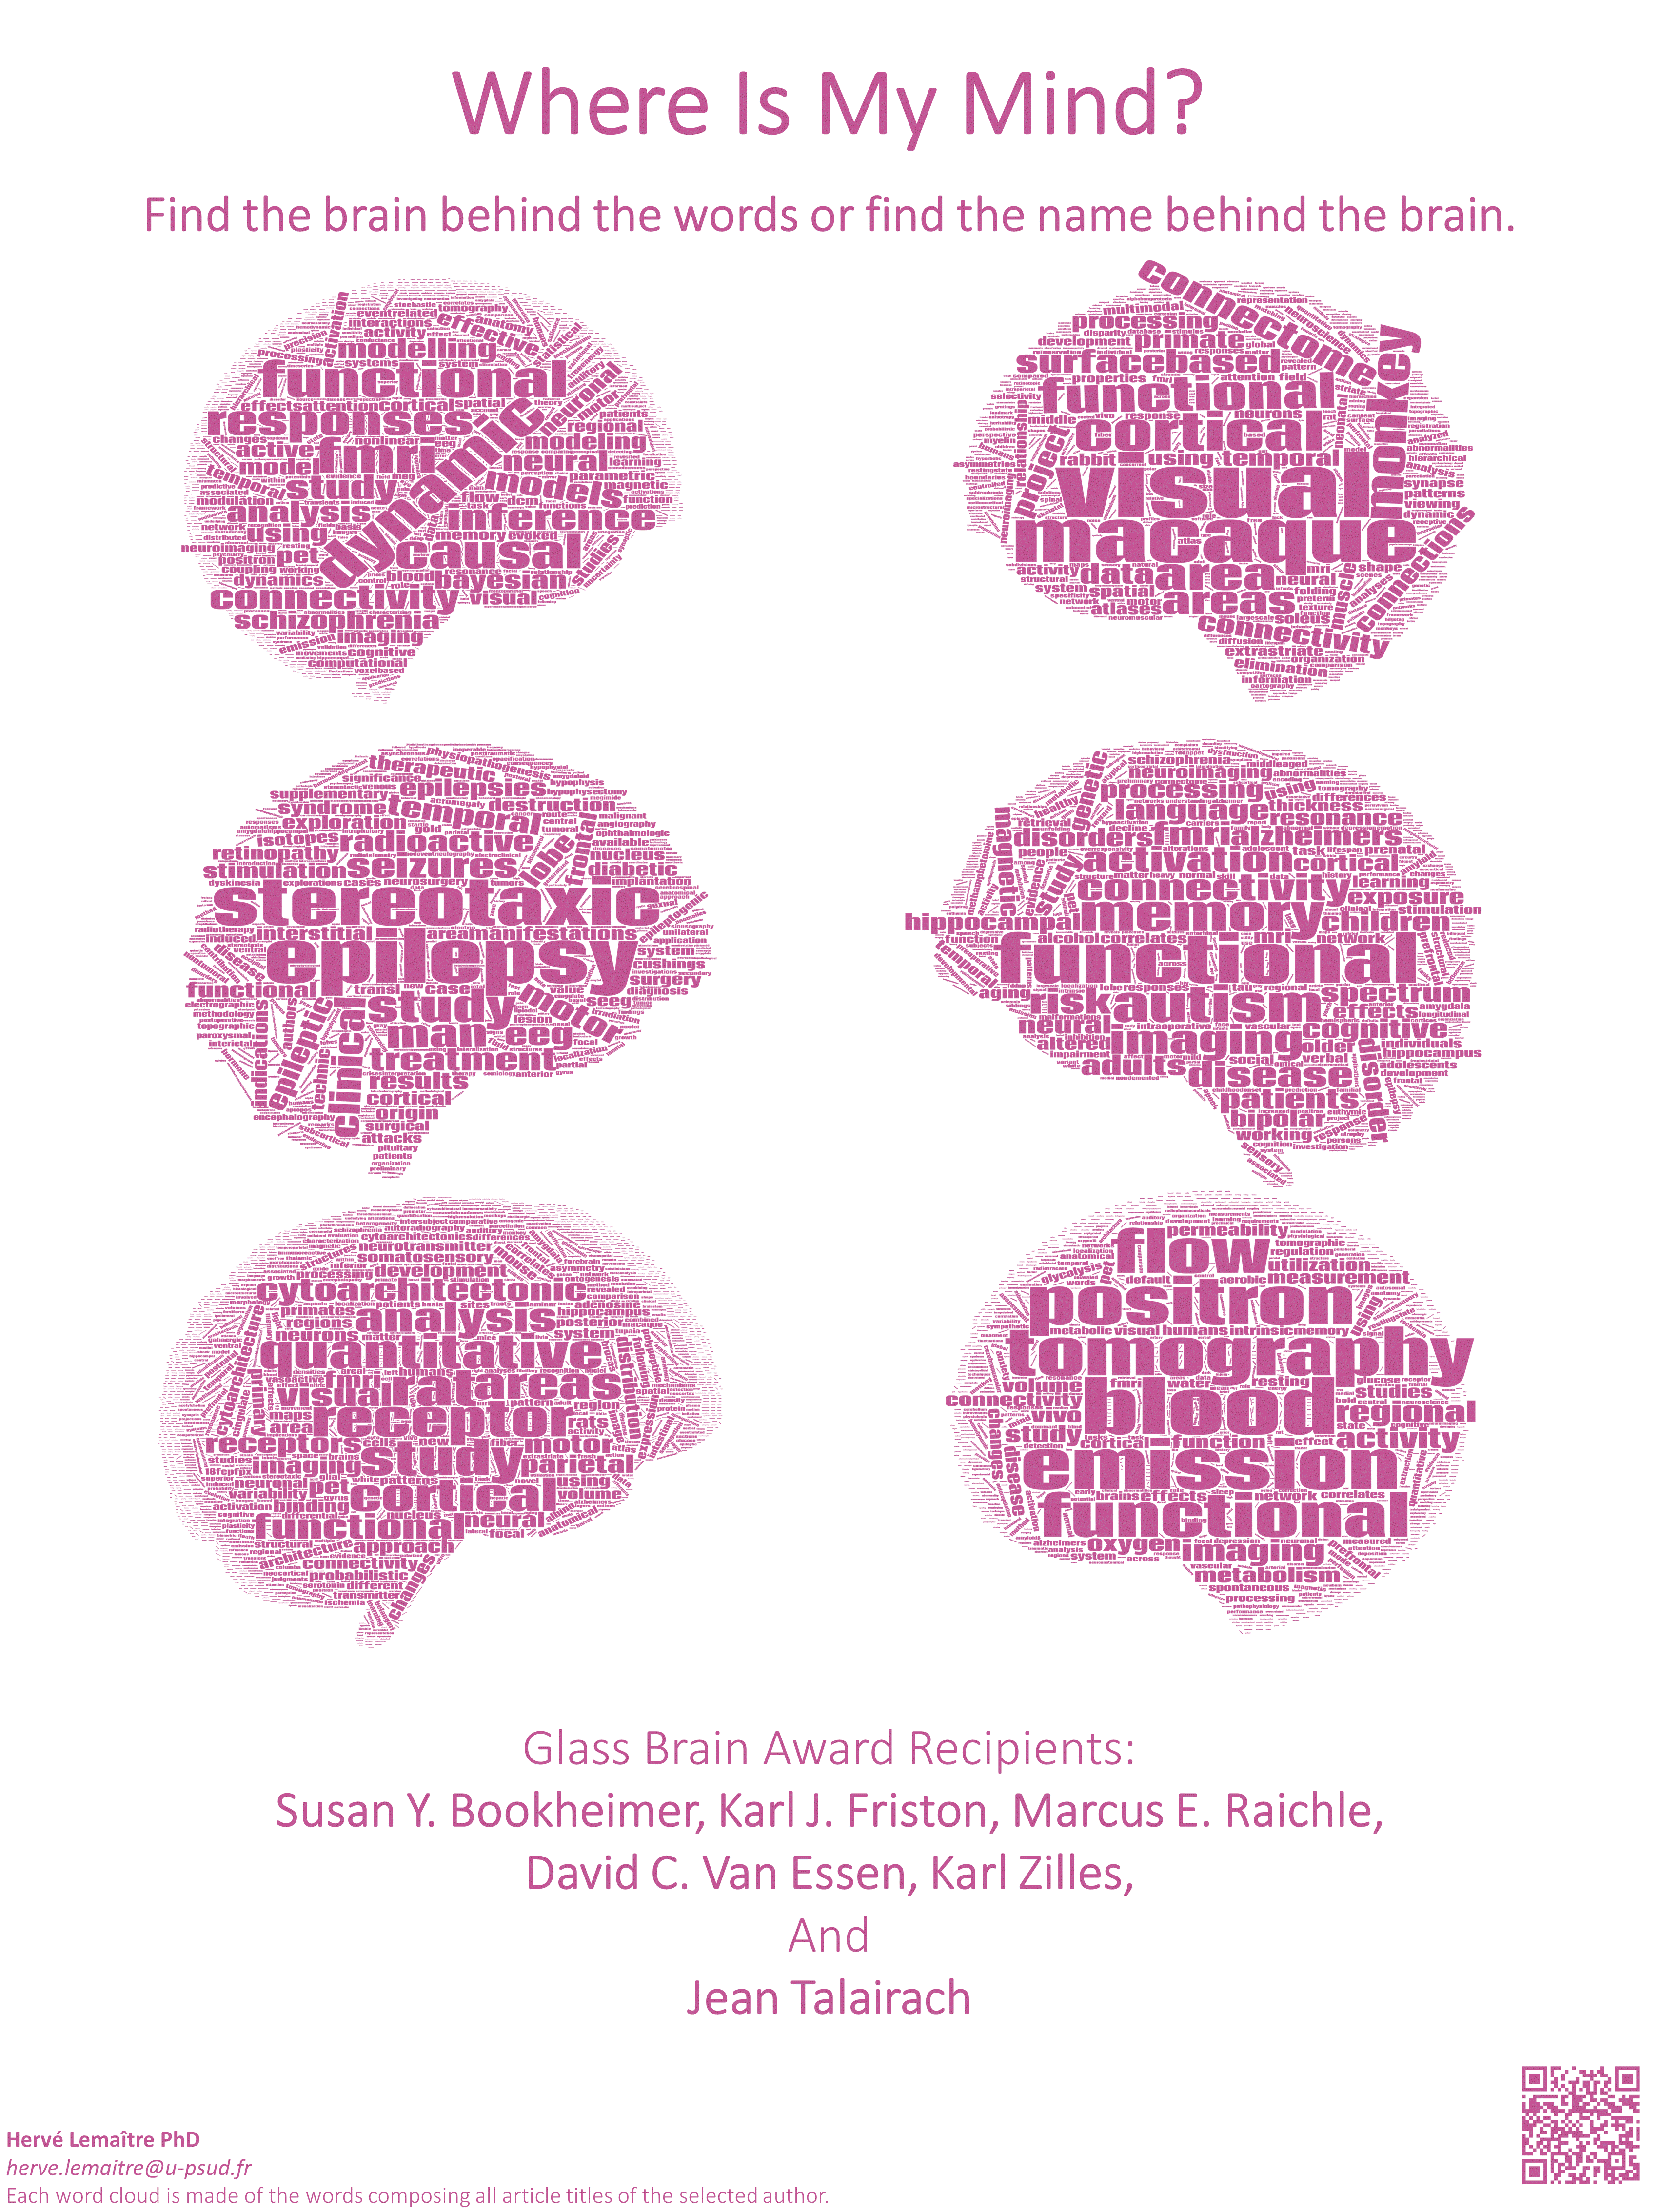
The above digital image was submitted to the Brain & Art Competition exhibited during the OHBM 2019 Annual Meeting in Rome.
The idea was to generate wordclouds based on the words composing the article titles of the selected authors. The following R script generates the corpus tables used in https://www.wordclouds.com to make the wordscloud figures.
#################################################################
# libraries

library(RISmed)
library(tm)

#################################################################
# select the author

terms="Bookheimer SY [Author]"
terms="Friston KJ [Author]"
terms="Raichle ME [Author]"
terms="Talairach J [Author]"
terms="Van Essen DC [Author]"
terms="Zilles K [Author]"

#################################################################
# general query

r=EUtilsSummary(terms, type='esearch', db='pubmed')
summary(r)

fetch=EUtilsGet(r)
titles=ArticleTitle(fetch)
abstracts=AbstractText(fetch)

#################################################################
# corpus table

# type of words
typetxt="titles"
#typetxt="abstracts"

datatxt=get(typetxt)

# load the corpus
datatxt.corpus <- Corpus(DataframeSource(data.frame(doc_id=(1:length(datatxt)),text=datatxt)))
# remove punctuations
datatxt.corpus <- tm_map(datatxt.corpus, removePunctuation)
# remove white space
datatxt.corpus <- tm_map(datatxt.corpus, stripWhitespace)
# lowercase
datatxt.corpus <- tm_map(datatxt.corpus, tolower)
# remove common english word, terms used and human brain mapping
datatxt.corpus <- tm_map(datatxt.corpus,function(x) removeWords(x, c(stopwords("english"),
                                                                     strsplit(terms," ")[[1]],
                                                                     "human","brain","cerebral","mapping","cortex")))
# create corpus table
tdm = TermDocumentMatrix(datatxt.corpus)
m = as.matrix(tdm)
v = sort(rowSums(m),decreasing=TRUE)
d = data.frame(word = names(v),freq=v)
summary(d)

# write csv
write.csv(d,paste(terms,".csv",sep=""),row.names=F)